 AMUN
01
Scan the Artifact
Aim your camera at an ancient statue, relief, stela, or museum display. Neural vision models immediately detect artifact boundaries and delineate inscription panels.
How Amun Works
Amun connects mobile computer vision with Egyptological scholarship. Photograph an artifact to identify its history, launch interactive audio guided tours, and reveal the ancient texts carved into stone.
01
Aim your camera at an ancient statue, relief, stela, or museum display. Neural vision models immediately detect artifact boundaries and delineate inscription panels.
02
When an artifact is identified, Amun launches an interactive audio tour—dynamically panning and spotlighting key details with synchronized expert narration.
03
Tap detected inscription areas to view transliteration and translations—retrieved from expert Egyptological publications or processed through our experimental AI pipeline.
Reading ancient Egyptian inscriptions accurately requires respecting the nuances of epigraphy. Rather than relying on generic AI that invents fictional translations, Amun uses a principled two-pathway system:
When an artifact is scanned, Amun visually identifies the piece and cross-references it with our own curated expert hieroglyph database.
Once identified, Amun immediately displays the verified, scholar-curated translation from our proprietary expert hieroglyphic records, providing 100% epigraphic fidelity with complete accuracy.
For inscriptions where no cataloged publication exists, Amun runs a multi-stage machine learning cascade. The pipeline isolates inscription columns, segments glyph instances, determines reading direction, classifies Gardiner codes, and translates sequence tokens.
* Important Note: This multi-stage AI translation pipeline is designed and intended to work experimentally on clear, well-preserved hieroglyphs.
Under the Hood
Detailed below is the computer vision and natural language processing architecture behind Amun's experimental hieroglyphic translation system, as engineered to process raw photographs into translated sentences:
A fine-tuned YOLOv8-seg model partitions the mobile photograph into distinct inscription columns and artifact boundaries. It handles complex multi-column stelae, statue back pillars, and relief registers, allowing each region to be extracted and processed independently.
YOLOv8-seg • mAP@50 ≈ 0.80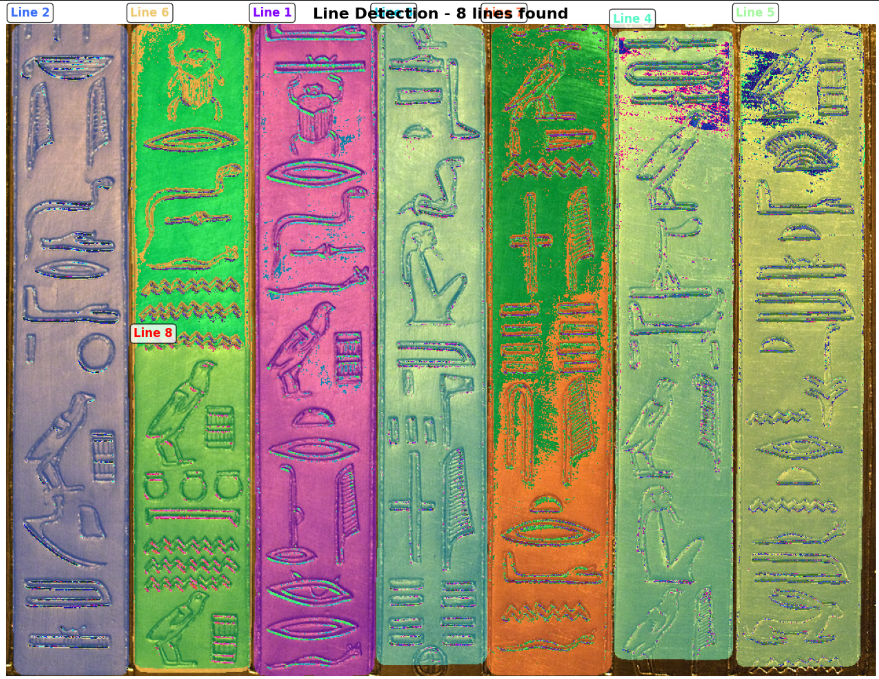
Within each detected column, Mask R-CNN extracts instance-level segmentation masks for individual hieroglyphic signs. Unlike naive rectangular bounding boxes, pixel-precise masks cleanly disentangle overlapping or touching signs carved into stone.
Mask R-CNN • AP50 ≈ 70.0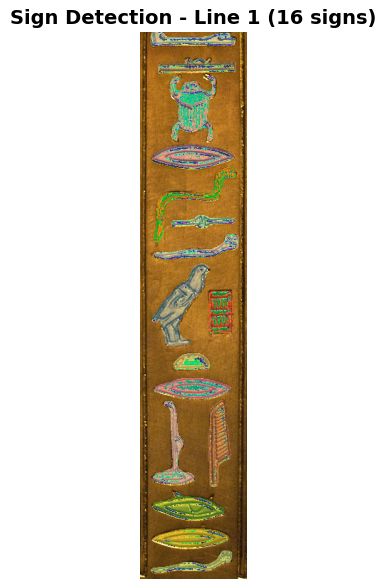
Ancient Egyptian script can be written left-to-right, right-to-left, or vertically in columns, facing the direction of human and animal signs. A ResNet18 classifier detects global reading direction (~85% accuracy), and a custom ray-casting Glyph Traversal algorithm groups signs into lines and orders them sequentially.
ResNet18 + Ray-Casting Glyph Traversal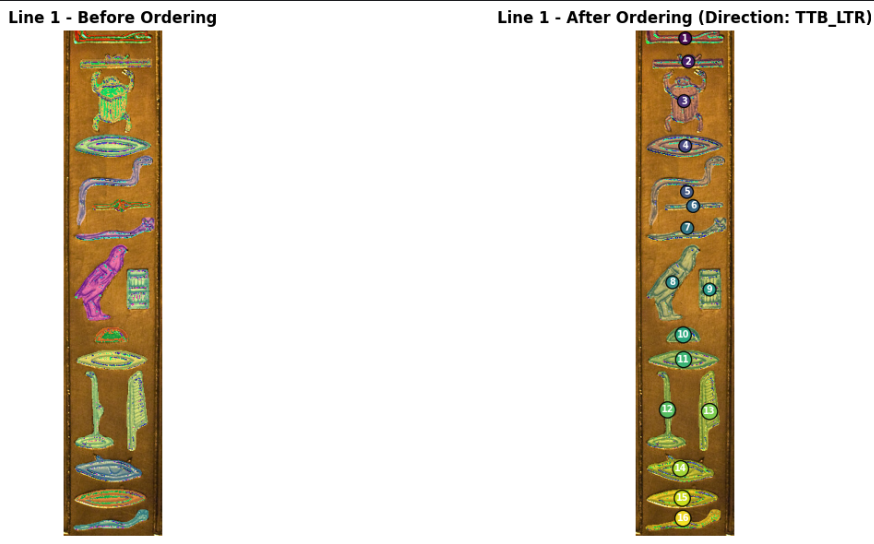
A Vision Transformer (ViT) fine-tuned with ArcFace metric learning maps each cropped glyph mask to its canonical Gardiner sign code across 362 classes. ArcFace enforces tight inter-class angular margins, providing robustness against stone weathering and varied carving depths.
ViT + ArcFace • 362 Classes • ~97% Accuracy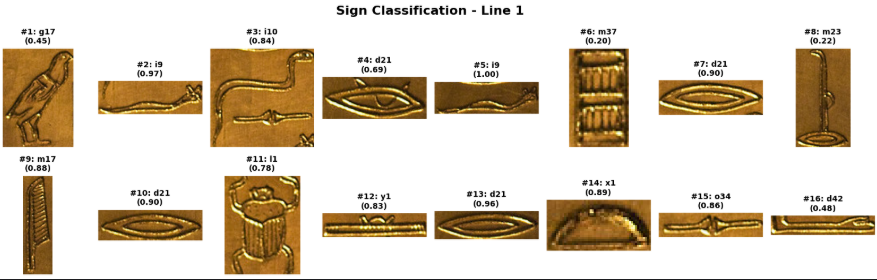
Egyptian hieroglyphic writing contains no spaces between words. A Transformer + CRF model predicts word boundaries (B/M/E/S tags) across Gardiner token sequences (~91% token accuracy). A Transformer encoder-decoder model then translates the transliterated tokens into English.
Transformer + CRF • BLEU 44.7 (short) / 10.3 (long)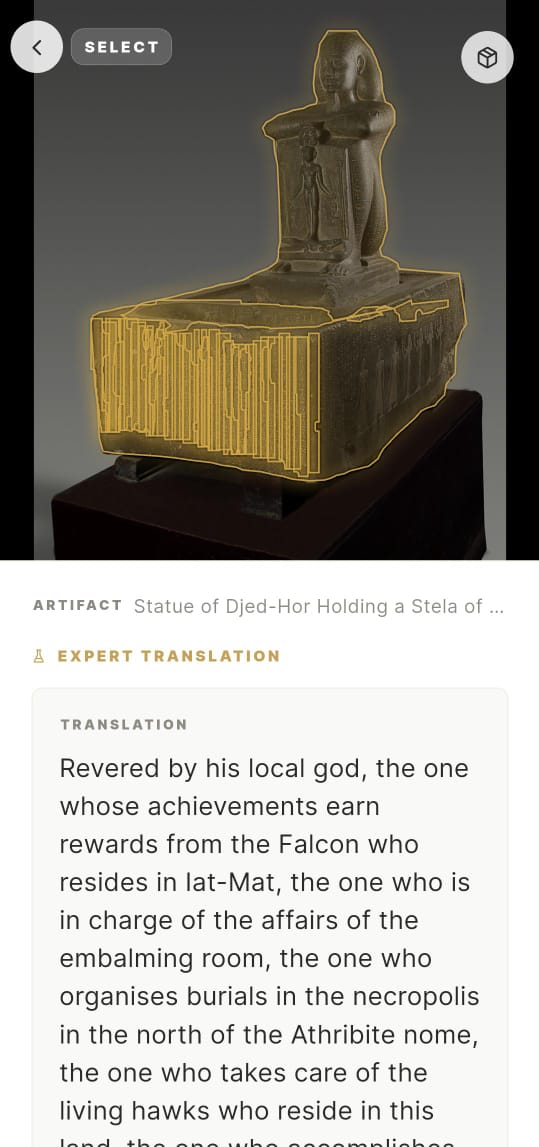
Amun is available now on the Apple App Store for iOS and Google Play for Android.